

DP-500 Exam Question 11
You need to configure the Sales Analytics workspace to meet the ad hoc reporting requirements.
What should you do?
What should you do?
DP-500 Exam Question 12
You have a Power Bl dataset that has the query dependencies shown in the following exhibit.
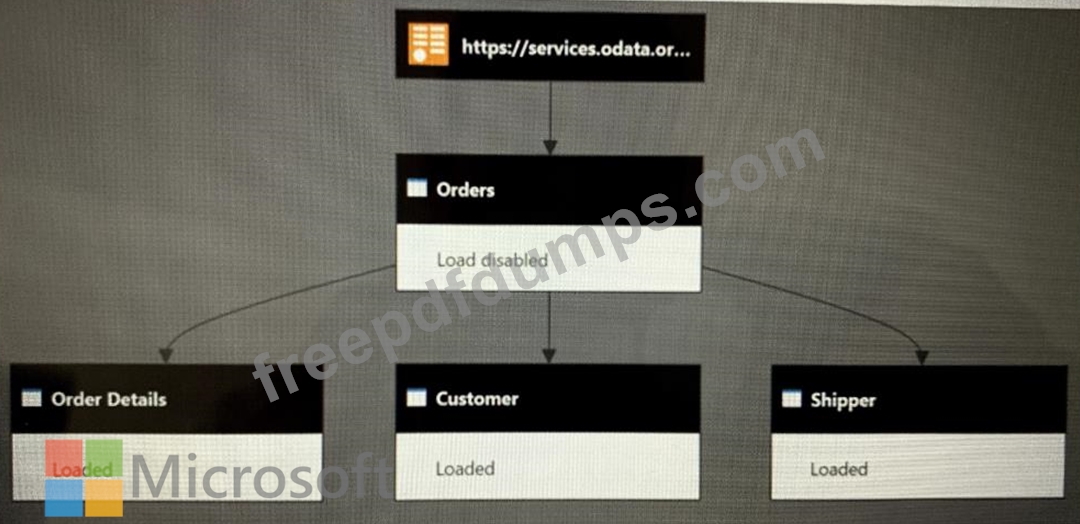
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
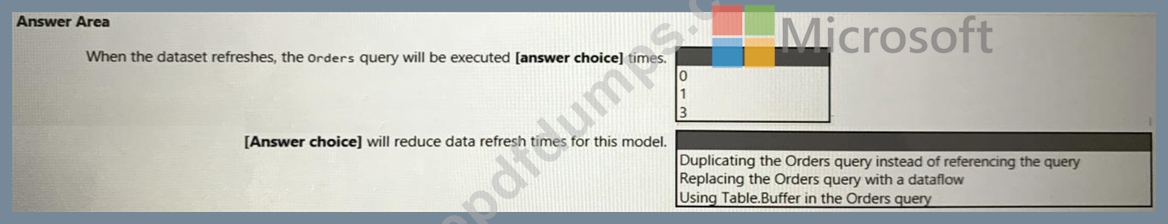
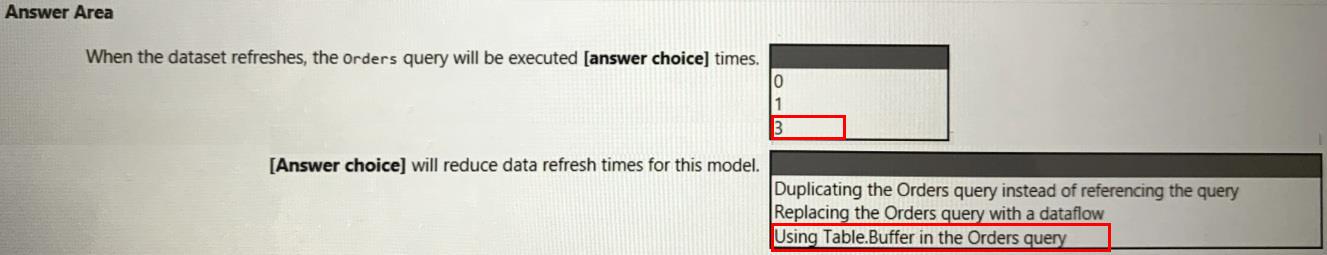
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
DP-500 Exam Question 13
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using an Azure Synapse Analytics serverless SQL pool to query a collection of Apache Parquet files by using automatic schema inference. The files contain more than 40 million rows of UTF-8-encoded business names, survey names, and participant counts. The database is configured to use the default collation.
The queries use open row set and infer the schema shown in the following table.

You need to recommend changes to the queries to reduce I/O reads and tempdb usage.
Solution: You recommend using openrowset with to explicitly define the collation for businessName and surveyName as Latim_Generai_100_BiN2_UTF8.
Does this meet the goal?
You are using an Azure Synapse Analytics serverless SQL pool to query a collection of Apache Parquet files by using automatic schema inference. The files contain more than 40 million rows of UTF-8-encoded business names, survey names, and participant counts. The database is configured to use the default collation.
The queries use open row set and infer the schema shown in the following table.
You need to recommend changes to the queries to reduce I/O reads and tempdb usage.
Solution: You recommend using openrowset with to explicitly define the collation for businessName and surveyName as Latim_Generai_100_BiN2_UTF8.
Does this meet the goal?
DP-500 Exam Question 14
You have a deployment pipeline for a Power BI workspace. The workspace contains two datasets that use import storage mode.
A database administrator reports a drastic increase in the number of queries sent from the Power BI service to an Azure SQL database since the creation of the deployment pipeline.
An investigation into the issue identifies the following:
One of the datasets is larger than 1 GB and has a fact table that contains more than 500 million rows.
When publishing dataset changes to development, test, or production pipelines, a refresh is triggered against the entire dataset.
You need to recommend a solution to reduce the size of the queries sent to the database when the dataset changes are published to development, test, or production.
What should you recommend?
A database administrator reports a drastic increase in the number of queries sent from the Power BI service to an Azure SQL database since the creation of the deployment pipeline.
An investigation into the issue identifies the following:
One of the datasets is larger than 1 GB and has a fact table that contains more than 500 million rows.
When publishing dataset changes to development, test, or production pipelines, a refresh is triggered against the entire dataset.
You need to recommend a solution to reduce the size of the queries sent to the database when the dataset changes are published to development, test, or production.
What should you recommend?
DP-500 Exam Question 15
You are using a Python notebook in an Apache Spark pool in Azure Synapse Analytics. You need to present the data distribution statistics from a DataFrame in a tabular view. Which method should you invoke on the DataFrame?