

Associate-Developer-Apache-Spark-3.5 Exam Question 26
A data engineer is building an Apache Spark™ Structured Streaming application to process a stream of JSON events in real time. The engineer wants the application to be fault-tolerant and resume processing from the last successfully processed record in case of a failure. To achieve this, the data engineer decides to implement checkpoints.
Which code snippet should the data engineer use?
Which code snippet should the data engineer use?
Associate-Developer-Apache-Spark-3.5 Exam Question 27
A data scientist is working on a large dataset in Apache Spark using PySpark. The data scientist has a DataFramedfwith columnsuser_id,product_id, andpurchase_amountand needs to perform some operations on this data efficiently.
Which sequence of operations results in transformations that require a shuffle followed by transformations that do not?
Which sequence of operations results in transformations that require a shuffle followed by transformations that do not?
Associate-Developer-Apache-Spark-3.5 Exam Question 28
You have:
DataFrame A: 128 GB of transactions
DataFrame B: 1 GB user lookup table
Which strategy is correct for broadcasting?
DataFrame A: 128 GB of transactions
DataFrame B: 1 GB user lookup table
Which strategy is correct for broadcasting?
Associate-Developer-Apache-Spark-3.5 Exam Question 29
A Data Analyst is working on the DataFramesensor_df, which contains two columns:
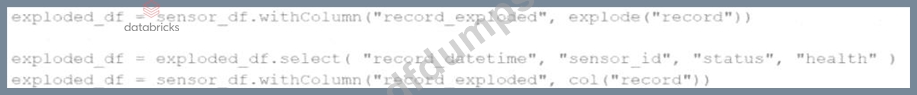
Which code fragment returns a DataFrame that splits therecordcolumn into separate columns and has one array item per row?
A)
B)

C)

D)

Which code fragment returns a DataFrame that splits therecordcolumn into separate columns and has one array item per row?
A)
B)
C)
D)
Associate-Developer-Apache-Spark-3.5 Exam Question 30
A data scientist wants each record in the DataFrame to contain:
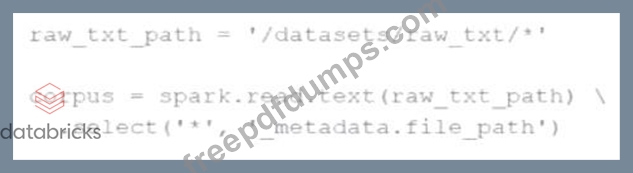
The first attempt at the code does read the text files but each record contains a single line. This code is shown below:
The entire contents of a file
The full file path
The issue: reading line-by-line rather than full text per file.
Code:
corpus = spark.read.text("/datasets/raw_txt/*") \
.select('*','_metadata.file_path')
Which change will ensure one record per file?
Options:
The first attempt at the code does read the text files but each record contains a single line. This code is shown below:
The entire contents of a file
The full file path
The issue: reading line-by-line rather than full text per file.
Code:
corpus = spark.read.text("/datasets/raw_txt/*") \
.select('*','_metadata.file_path')
Which change will ensure one record per file?
Options: