

DP-203 Exam Question 31
You implement an enterprise data warehouse in Azure Synapse Analytics.
You have a large fact table that is 10 terabytes (TB) in size.
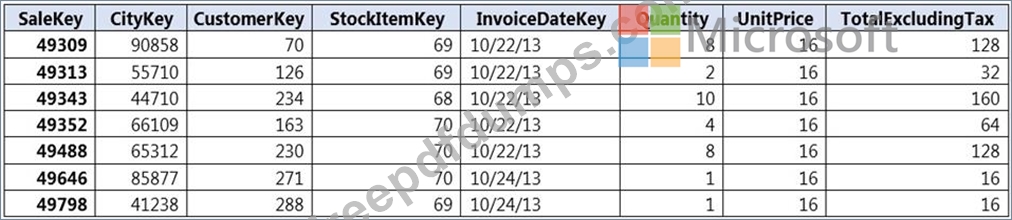
Incoming queries use the primary key SaleKey column to retrieve data as displayed in the following table:
You need to distribute the large fact table across multiple nodes to optimize performance of the table.
Which technology should you use?
You have a large fact table that is 10 terabytes (TB) in size.
Incoming queries use the primary key SaleKey column to retrieve data as displayed in the following table:
You need to distribute the large fact table across multiple nodes to optimize performance of the table.
Which technology should you use?
DP-203 Exam Question 32
You have an Azure Data Factory pipeline that performs an incremental load of source data to an Azure Data Lake Storage Gen2 account.
Data to be loaded is identified by a column named LastUpdatedDate in the source table.
You plan to execute the pipeline every four hours.
You need to ensure that the pipeline execution meets the following requirements:
* Automatically retries the execution when the pipeline run fails due to concurrency or throttling limits.
* Supports backfilling existing data in the table.
Which type of trigger should you use?
DP-203 Exam Question 33
You are designing a data mart for the human resources (MR) department at your company. The data mart will contain information and employee transactions. From a source system you have a flat extract that has the following fields:
* EmployeeID
* FirstName
* LastName
* Recipient
* GrossArnount
* TransactionID
* GovernmentID
* NetAmountPaid
* TransactionDate
You need to design a start schema data model in an Azure Synapse analytics dedicated SQL pool for the data mart.
Which two tables should you create? Each Correct answer present part of the solution.
DP-203 Exam Question 34
You are designing an anomaly detection solution for streaming data from an Azure IoT hub. The solution must meet the following requirements:
* Send the output to Azure Synapse.
* Identify spikes and dips in time series data.
* Minimize development and configuration effort.
Which should you include in the solution?
* Send the output to Azure Synapse.
* Identify spikes and dips in time series data.
* Minimize development and configuration effort.
Which should you include in the solution?
DP-203 Exam Question 35
You have an Azure Data Factory pipeline named Pipeline1!. Pipelinel contains a copy activity that sends data to an Azure Data Lake Storage Gen2 account. Pipeline 1 is executed by a schedule trigger.
You change the copy activity sink to a new storage account and merge the changes into the collaboration branch.
After Pipelinel executes, you discover that data is NOT copied to the new storage account.
You need to ensure that the data is copied to the new storage account.
What should you do?
You change the copy activity sink to a new storage account and merge the changes into the collaboration branch.
After Pipelinel executes, you discover that data is NOT copied to the new storage account.
You need to ensure that the data is copied to the new storage account.
What should you do?