

DP-203 Exam Question 36
You are creating an Azure Data Factory data flow that will ingest data from a CSV file, cast columns to specified types of data, and insert the data into a table in an Azure Synapse Analytics dedicated SQL pool. The CSV file contains columns named username, comment and date.
The data flow already contains the following:
* A source transformation
* A Derived Column transformation to set the appropriate types of data
* A sink transformation to land the data in the pool
You need to ensure that the data flow meets the following requirements;
* All valid rows must be written to the destination table.
* Truncation errors in the comment column must be avoided proactively.
* Any rows containing comment values that will cause truncation errors upon insert must be written to a file in blob storage.
Which two actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point
DP-203 Exam Question 37
You are designing a sales transactions table in an Azure Synapse Analytics dedicated SQL pool. The table will contains approximately 60 million rows per month and will be partitioned by month. The table will use a clustered column store index and round-robin distribution.
Approximately how many rows will there be for each combination of distribution and partition?
Approximately how many rows will there be for each combination of distribution and partition?
DP-203 Exam Question 38
You have a table in an Azure Synapse Analytics dedicated SQL pool. The table was created by using the following Transact-SQL statement.

You need to alter the table to meet the following requirements:
* Ensure that users can identify the current manager of employees.
* Support creating an employee reporting hierarchy for your entire company.
* Provide fast lookup of the managers' attributes such as name and job title.
Which column should you add to the table?
DP-203 Exam Question 39
You plan to perform batch processing in Azure Databricks once daily.
Which type of Databricks cluster should you use?
Which type of Databricks cluster should you use?
DP-203 Exam Question 40
You build an Azure Data Factory pipeline to move data from an Azure Data Lake Storage Gen2 container to a database in an Azure Synapse Analytics dedicated SQL pool.
Data in the container is stored in the following folder structure.
/in/{YYYY}/{MM}/{DD}/{HH}/{mm}
The earliest folder is /in/2021/01/01/00/00. The latest folder is /in/2021/01/15/01/45.
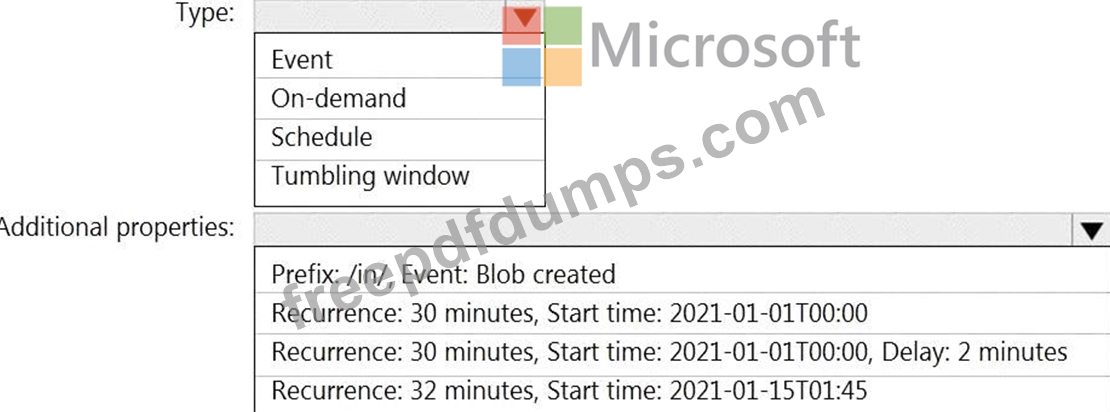
You need to configure a pipeline trigger to meet the following requirements:
* Existing data must be loaded.
* Data must be loaded every 30 minutes.
* Late-arriving data of up to two minutes must he included in the load for the time at which the data should have arrived.
How should you configure the pipeline trigger? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Data in the container is stored in the following folder structure.
/in/{YYYY}/{MM}/{DD}/{HH}/{mm}
The earliest folder is /in/2021/01/01/00/00. The latest folder is /in/2021/01/15/01/45.
You need to configure a pipeline trigger to meet the following requirements:
* Existing data must be loaded.
* Data must be loaded every 30 minutes.
* Late-arriving data of up to two minutes must he included in the load for the time at which the data should have arrived.
How should you configure the pipeline trigger? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.

